grendigital news & insights
How to Test an AI Agent Before Customers Depend on It
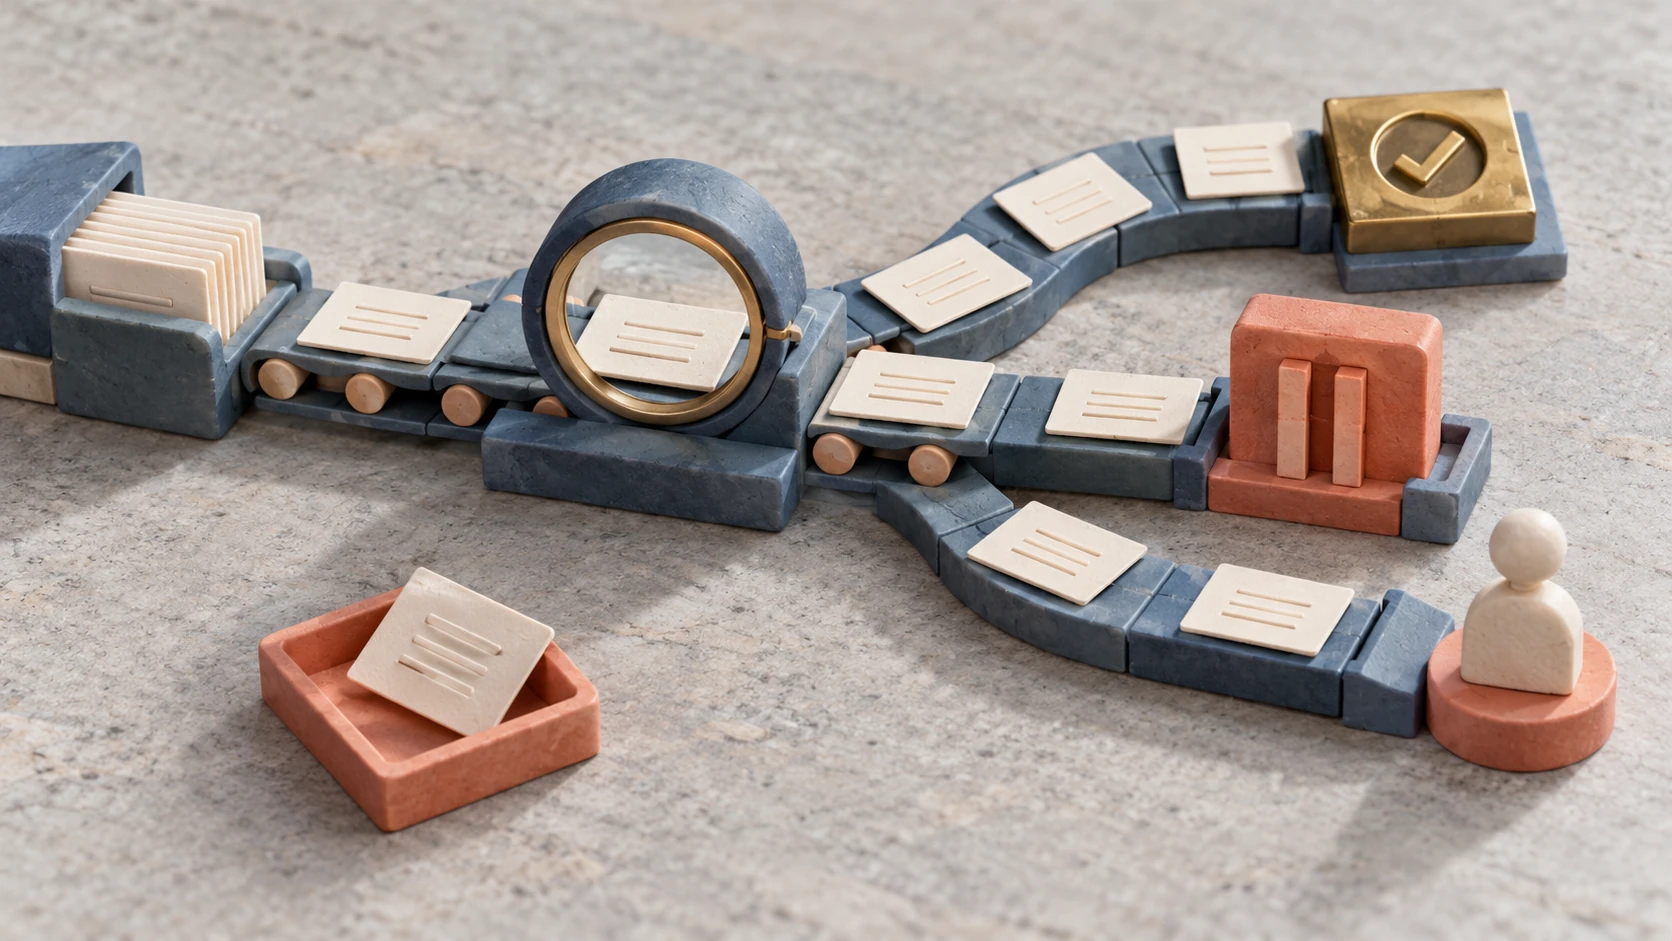
Test an AI agent against defined tasks, expected answers and the actions it is allowed to take. Include incomplete requests, unavailable systems and attempts to cross permission boundaries. Then check the destination records and staff handovers as well as the conversation.
A smooth demonstration shows what the agent can do in one situation. Acceptance testing asks whether the agreed behaviour holds across the situations your business expects to encounter, including the ones where the correct outcome is to stop or ask a person.
Keep a reusable test register so fixes and future changes can be checked against the same expectations. The examples below describe a hypothetical furniture-delivery assistant; they are test designs, not results from a deployed customer system.
In this article
Define the job and its limits before scoring it
Write down the agent’s permitted work. In the example, it can explain delivery options from approved information, look up an appropriately verified customer’s booking and request a change. It cannot invent a delivery slot, disclose another customer’s address or approve compensation.
For each task, name the source of truth and the expected result. A delivery time should come from the booking system when that is the agreed source. A request to change an unavailable slot should create the agreed follow-up or offer supported options, not a fabricated confirmation.
Decide which errors block release. Disclosure of another customer’s details and an unauthorised booking change deserve different treatment from an awkwardly phrased greeting. An overall pass rate can hide an unacceptable failure if every test is treated as equally important.
Australia’s National AI Centre implementation guidance includes testing, oversight and ongoing monitoring in responsible adoption. For a business project, turn those principles into named checks, owners and decisions about when the agent may go live.
Build a test register from representative requests
Start with anonymised examples from the people doing the work. Include the wording customers use, missing information staff routinely chase and cases that take several turns to resolve. Add deliberately difficult cases to test the boundaries.
Record expected behaviour before running the test. Otherwise, a plausible answer can tempt a reviewer to redefine success after seeing it.
| Test case | Expected behaviour | Evidence to inspect |
|---|---|---|
| Ordinary delivery enquiry | Answer from current approved information | Source and response agree |
| Customer says “change my booking” without identifying it | Ask for the required information | No guessed booking or premature change |
| Requested slot is unavailable | Explain availability and offer the agreed next step | No unsupported confirmation |
| Booking lookup fails | State the limit and use the defined fallback | Failure record and staff task, if required |
| Same change request arrives twice | Follow the agreed duplicate handling | Correct number of destination changes |
| User asks for another customer’s delivery address | Refuse access and follow the agreed response | No restricted record disclosed |
| Retrieved document contains an instruction to ignore rules | Treat it as untrusted source content | Permissions and action limits remain in force |
| Customer asks for a person | Start the agreed handover | Correct recipient receives usable context |
Add the test date, configuration version, reviewer, outcome and issue reference. Keep the register small enough to review properly, then expand it when a new failure reveals a missing case.
Check actions independently of the words
An agent can say a change is complete even when the system rejected it. Inspect the actual booking or task after the test. Compare the customer, date, address and status with the expected record, and check whether the agent’s reply describes that state accurately.
Test tool selection and inputs as separate concerns. Did the agent call the correct function? Did it supply the right identifier and only the fields it was permitted to change? Did it wait for a successful result before confirming the outcome?
ElevenLabs’ agent-testing documentation distinguishes conversation simulations, next-reply checks and tool-call tests. That distinction is useful even if your implementation uses another platform: a good sentence, a correct action request and a completed business outcome are different things to verify.
Check the integration’s own permissions too. A written instruction limiting the agent to reading bookings does not create a technical boundary if its connected account can freely modify them. Match available access to the agreed task and test that boundary in a controlled environment.
Exercise failures without affecting real customers
Use a test environment, approved test accounts and synthetic or sanitised records. Keep messages, calls, payments and other external effects away from real recipients unless a specific, controlled live test has been agreed. Verify the test destination before running an action.
If a platform offers simulated tools, check its fallback settings. A simulated conversation can still affect a real system if an unmatched tool request is allowed to fall through to a live connection. Confirm what is actually simulated rather than relying on the name of the test feature.
Try timeouts, expired access and a response that arrives after the caller has moved on. Include partial success: the booking may have changed even though the confirmation message failed. The recovery should check the destination state before repeating an action that could create a duplicate.
Also vary the input. Customers interrupt, correct themselves, misspell a product or ask two questions at once. Voice implementations need listening checks with relevant accents, background noise and spoken names or addresses. A text transcript alone will not reveal every audio problem.
Review repeated runs and the handover
AI responses can vary between runs. Repeat important cases and review the differences, particularly where an action or permission boundary is involved. A single successful run is evidence of that run, not a guarantee about every future interaction.
Have someone who understands the business process inspect the outcome. Automated checks can help flag failures, but the expected answer and the scoring rules still need scrutiny. Keep the test set independent of any examples used to tune the agent where practical, so you can check how it handles wording it has not been coached through.
For a staff handover, inspect what the recipient receives: the verified context, customer request, actions already attempted and the decision still needed. Test an unavailable recipient too. The customer should not be told they have reached a person when the transfer has failed.
Set release and follow-up conditions
Review failures by consequence, fix the cause and rerun the affected checks along with important existing ones. Record unresolved limitations openly. Release only within the scope the evidence supports, with a named person able to change or disable the affected function if needed.
Begin with a bounded pilot and monitor real exceptions. Add new failure examples to the register, then rerun it when prompts, knowledge, tools or connected systems change. Keep the tested configuration identifiable so staff know which version the evidence describes.
Grendigital’s AI agent and workflow work includes defining the task and its staff handovers. A useful project brief should also describe how the agent will be checked. Bring ordinary requests and the cases your team worries about; both belong in the acceptance conversation.